A general-purpose AI model knows a great deal about the world and nothing about your business. It hasn’t read your contracts, policies, or product catalogue, and it has no idea what your customers bought last quarter.
Every team building a business AI hits the same question sooner or later: do you teach the model your world, or hand it your documents when it needs them?
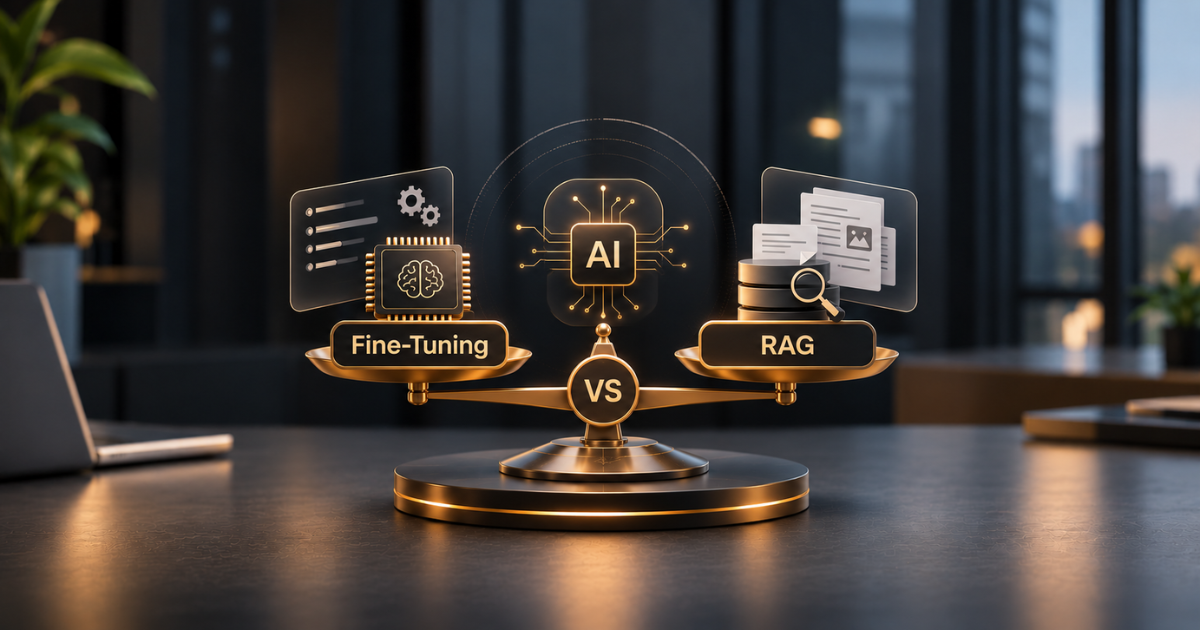
That’s the real choice behind fine-tuning vs RAG. Retrieval-augmented generation, usually shortened to RAG, looks up the right information when a question is asked. Fine-tuning changes the model itself by training it further on your examples.
This guide explains how each works, where each fits, what they cost you in effort and risk, and how to choose without burning a quarter on the wrong one.
What Is RAG?
RAG connects a model to your own content. When someone asks a question, the system searches your documents, retrieves the most relevant passages, and passes them to the model along with the question. The model then writes its answer from that material rather than relying on memory.
The model itself remains unchanged. All the work happens in the layer around it: how your content is split up, indexed and searched.
That’s why the quality of your knowledge base matters so much, a point we made in our guide to implementing agentic AI in Dynamics 365 Customer Service.
If you want to see how agents reach live business systems, our piece on connecting Copilot Studio agents to external data with custom MCP servers covers a closely related idea.
What Is Fine-Tuning?
Fine-tuning takes an existing model and trains it further on examples you provide. Those examples show the model the style, format or behaviour you want, so it learns to produce them without being told every time.
Think of it as changing how the model behaves rather than what it can look up. It’s good for teaching a consistent tone, a strict output format or a specialist way of handling a narrow task.
It’s a poor way to store facts, because anything the model absorbed during training is baked in and can’t easily be updated or traced back to a source.
A Comparative Overview of Fine-Tuning and RAG
| Factor | RAG | Fine-tuning |
| What it changes | What the model can see | How the model behaves |
| Best for | Answers grounded in your documents and data | Consistent style, format or specialist behaviour |
| Keeping it current | Update the content, no retraining | Retrain when things change |
| Source traceability | Can point to where an answer came from | Hard to trace an answer to a source |
| Effort up front | Search, indexing and content quality | Building and checking a good training set |
| Main risk | Poor retrieval returns poor answers | Stale knowledge and hidden bias in training data |
When RAG Is the Right Choice
For most business questions, RAG is where we’d start. If the goal is to answer from your own information, such as policies, product details, case histories or technical manuals, RAG fits naturally.
It works well when your information changes often, because you update a document rather than retraining a model. It lets you show where an answer came from, which helps people trust it and makes it easier for auditors to check it.
It also respects permissions better, since you can limit what each user’s questions are allowed to retrieve. And it usually gets you to a working pilot faster, because you’re connecting content rather than preparing training data.
When Fine-Tuning Is the Right Choice
Fine-tuning earns its place when the problem is behaviour, not knowledge. A few signs you’re in that territory:
- Consistent tone or format. You need every response in a precise house style or a strict structure that prompting alone can’t hold reliably
- A narrow, repeated task. The same kind of input arrives thousands of times, and a smaller tuned model could do it faster and more cheaply
- Specialist language. Your field uses terms and conventions that a general model keeps getting slightly wrong
- Stable requirements. The behaviour you want won’t change every few weeks, so retraining won’t become a constant chore
If your reason for fine-tuning is “we want it to know our facts”, pause. That’s usually a RAG problem in disguise.
Using Both Together
The two aren’t rivals. A common pattern is to pair a model fine-tuned to behave as you want with RAG to supply the facts it needs. The fine-tuned model handles tone, structure and task discipline, while retrieval keeps the content accurate and current.
Most teams don’t need that on day one. Start with RAG, see where the answers fall short, and add fine-tuning only when you can pinpoint a behaviour problem that retrieval can’t fix. Prompting and good retrieval solve more than people expect.
Cost, Maintenance and Risk
Neither route is free, and the costs appear in different places. RAG costs you in content and search quality: messy, duplicated or out-of-date documents lead directly to messy answers.
Fine-tuning costs you in training data and upkeep; someone has to build good examples, test the results and repeat the process when your needs change.
Each approach also carries risks worth noting. A RAG system can retrieve the wrong passage and present it with confidence. A fine-tuned model can sound authoritative while repeating something that’s now out of date.
In both cases, the only honest way to measure quality is to have people review the output on real tasks. Our guide to the Sales Bench shows how to build a simple scorecard for that. We haven’t put figures here because pricing varies by platform and changes often, so confirm current rates with your provider.
Security and Governance
Where your data goes matters as much as which technique you choose. With RAG, the question is who can retrieve what. If your permissions are loose, a helpful assistant can surface documents that were never meant to be seen.
With fine-tuning, the question is what ends up inside the model, because training data can’t easily be removed once it’s learned.
Either way, give each AI system its own identity, its own permissions and a record of what it did. We cover that in our guide to securing AI agents with Microsoft Entra ID, and the wider principles in responsible AI in practice.
How to Decide
A few simple questions settle most cases.
Is the problem about knowledge or behaviour? Knowledge points to RAG; behaviour points to fine-tuning. How often does the information change? If it changes often, RAG.
Do people need to see where an answer came from? If so, RAG. Is the task narrow, repeated and stable? Then fine-tuning may be worth it. And do you have a clean, well-labelled set of examples? Without one, you can’t start fine-tuning.
What Has to Be Right First
Most of the work sits in the basics, whichever route you pick.
- Clean content. Up-to-date, de-duplicated documents with clear owners, because the model is only as good as what it reads
- Joined-up data. A single view of your customers and records, which our guides to solving data silos in local government and a single customer view both explain
- Sensible pipelines. Data that lands in a structured, reliable way, as covered in our guide to building modern pipelines in Microsoft Fabric
- Tight permissions. Access rules that stop an assistant from retrieving more than the user could
- A narrow start. One use case, a small group of testers and a way to measure the results before anything goes wide
If you’re building agents on top of this, our piece on building AI agents in the Power Platform covers the agent side.
Final Thoughts
Fine-tuning vs RAG isn’t a contest with a single winner. RAG gives a model your knowledge, while fine-tuning shapes its behaviour. Most business AI starts with RAG and adds tuning only when there’s a clear reason.
Success is rarely decided by the technique. It’s clean content, sensible permissions, honest testing, and a clear owner for every system.
If you’d like help choosing and building the right approach, our D365 integration and BI and Data Science services team can plan and connect your data, and our AI Enablement Programme takes teams from first experiment to production without the usual false starts.
As an ISO 27001-certified Microsoft partner, we ensure governance is in place before an AI system accesses live business data.
Book a free assessment, and we’ll tell you honestly where to begin, no hard sell.
Frequently Asked Questions
What is the difference between fine-tuning and RAG?
RAG retrieves relevant information from your content when a question is asked and provides it to the model. Fine-tuning further trains the model on your examples to change how it behaves. RAG supplies knowledge; fine-tuning shapes behaviour.
Is RAG better than fine-tuning?
For answering questions about your own documents and data, RAG is usually the better starting point. Fine-tuning is better for consistent style, strict formats, or narrow specialist tasks. Neither is better in every case.
Can I use fine-tuning and RAG together?
Yes. A common pattern is to use a tuned model for tone and task discipline, with RAG supplying current facts. Most teams start with RAG and add tuning later if needed.
Does fine-tuning teach a model my company’s facts?
Not reliably. Facts absorbed during training are hard to update or trace to a source, so RAG is normally the better way to give a model your knowledge.
Which approach is easier to keep up to date?
RAG. You update the underlying content, and the system uses it straight away. Fine-tuned models usually need retraining when your information or requirements change.